AI AgentsPart 50
palaniappan p9 min
AI Agent for eCommerce Refund Investigation (2026)
This refund means 5 screens, a polite shopper, and a package that says delivered. Build the evidence first. Recommend. Do not issue the refund in week one.
FactualMinds Blog
Expert perspectives on AWS cloud consulting, generative AI, and enterprise solutions.
This refund means 5 screens, a polite shopper, and a package that says delivered. Build the evidence first. Recommend. Do not issue the refund in week one.
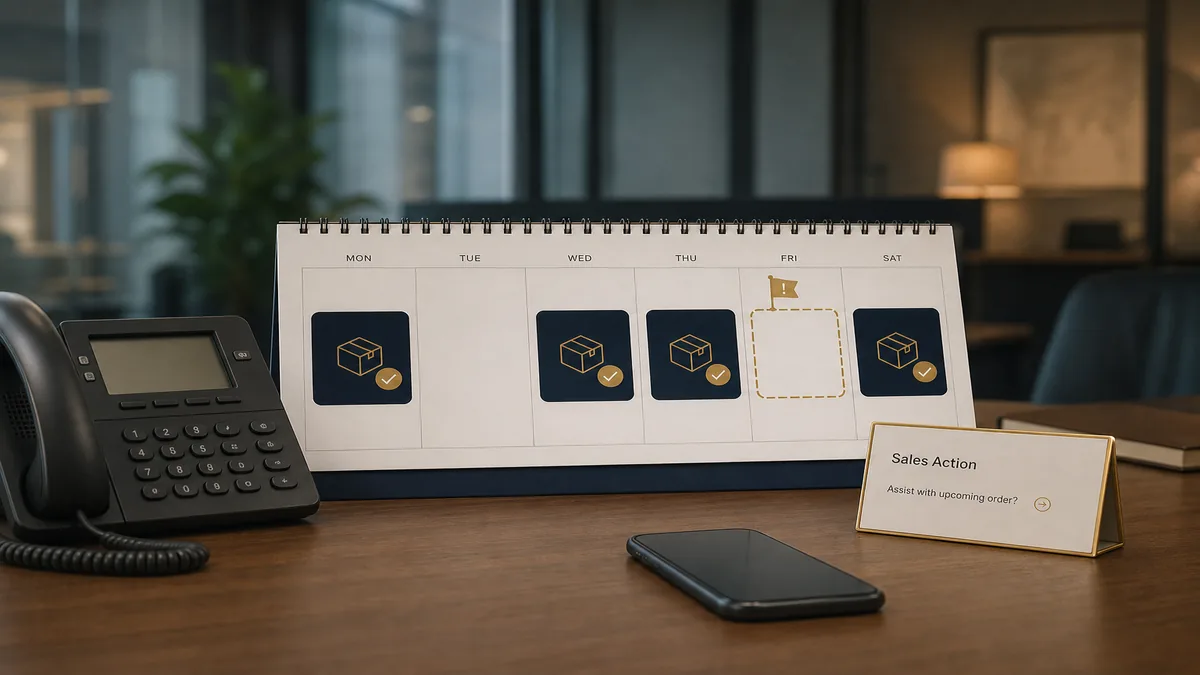
Monday, the account calendar. A ~30-day cadence that goes quiet is an AM task — not a "we miss you" email. Day 38 is a queue row. Sales still decides who speaks.
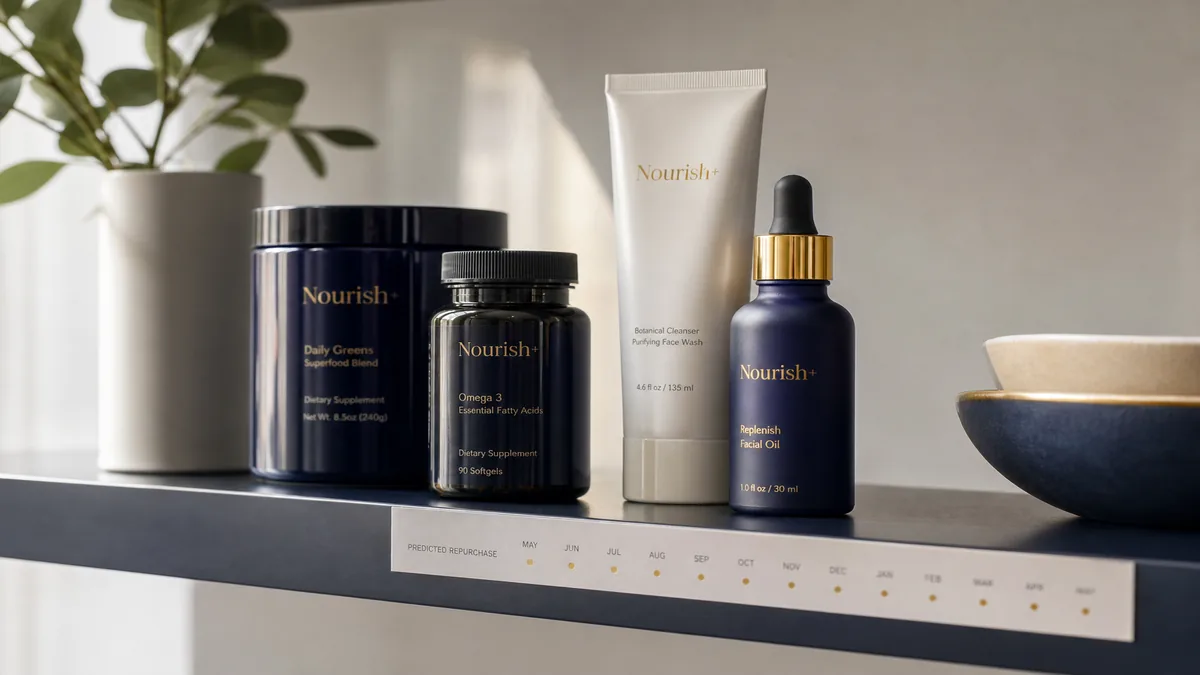
Vitamins due next week — unless they already subscribe. Predict the window, draft one reminder, never charge the card. Cart abandonment is 70.22%; that is not a refill rate.
The serial-returner spreadsheet becomes "you are fraudulent" in a ticket. Risk bands stay internal. High freezes auto-refund. A person still owns the accusation. The ~$791/mo platform cost floor at 50,000 sessions is planning cost, not fraud recovered.
Finance asks why revenue dropped last week. Someone answers with a TikTok story and no tools. Hop table with evidence per step — Baymard 70.22% is industry context, not your diagnosis.
Monday, the wholesale counter. An agent looks up their net, not the public product page. 3 signed-in roles keep the price book closed. No payment capture.
Shoppers click through from ChatGPT and Perplexity. Adobe measured July 2026 AI-referral traffic to U.S. retail +62% YoY. Instrument that channel before you buy a GEO rank.
Baymard still measures average cart abandonment at 70.22%. A shopping agent that quotes yesterday's stock makes that worse. Score 13 checks before you invite a copilot.
For the person who will build your first store agent on AWS — not a Shopify plug-in. One lookup workflow this week; refunds wait for a person. Planning silhouette ~$791/mo at 50K sessions.
Autonomy is per action, not one store-wide dial. The public worksheet uses a $75 refund ceiling — yours belongs in Policy, not a prompt. Delay notices can go fully automated when the template is fixed.
Five program levels from FAQ assistant to multi-agent ops. Level 5 is optional. McKinsey found only 23% scaling in at least one function.
Score org-wide readiness out of 30. Below 16 out of 30, do not let it change orders. McKinsey found 62% experimenting and 23% scaling — still a minority per function.